What Is a World Model? A Plain-English Guide to AI That Learns How Reality Works
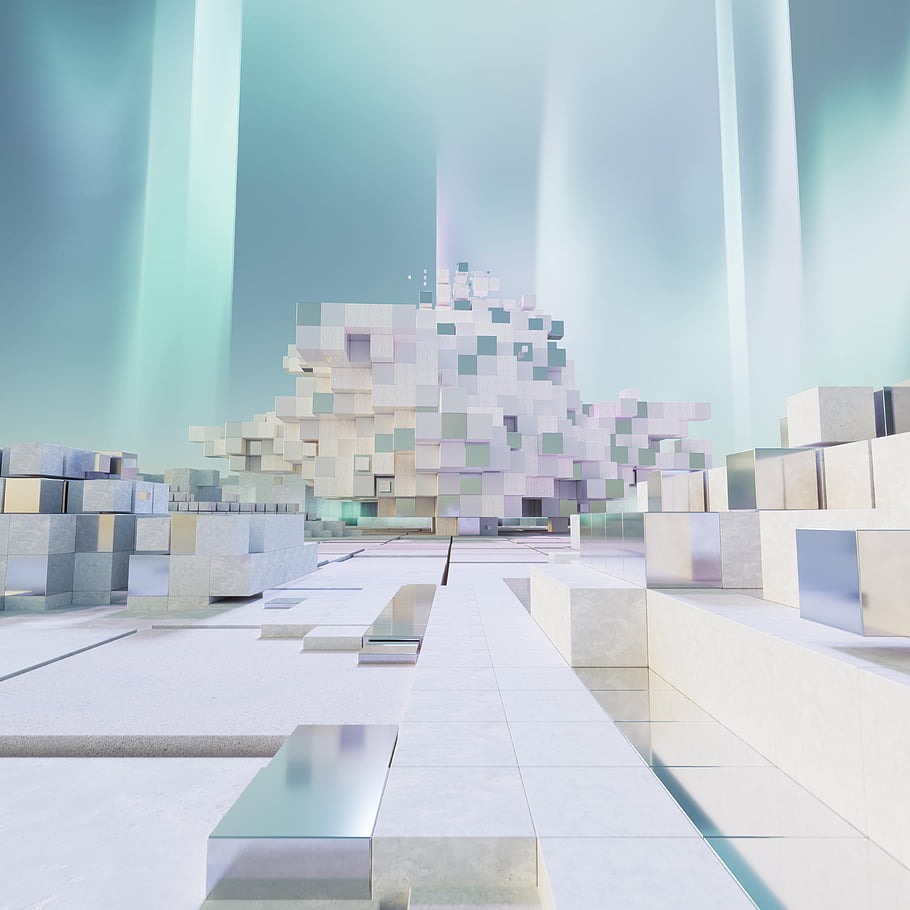
Photo: Hippopx (public domain). A world model builds places like this — then lets you walk through them and change them.
A chatbot predicts the next word. An image generator predicts the next pixel. A world model predicts the next moment. It is an AI system that has learned how the world behaves — how objects move, fall, collide and change — and uses that knowledge to generate a scene that keeps behaving as you explore it and change it. This guide explains what world models are, how they work, what they are already used for, and where they still break down.
The short answer
A world model is an AI model trained largely on video that has learned the patterns of the physical world — gravity pulls things down, a ball rolls until friction stops it, a door opens when pushed — well enough to simulate what happens next. Give it a photo or a prompt and it generates an interactive environment you can move through in real time; change something — the weather, the camera angle, a character’s action — and the scene updates, frame by frame, in a way that stays roughly consistent with how the real world would respond.
The key difference from a video generator is interactivity. A video generator renders a fixed clip. A world model renders a place: it keeps generating the next frame based on what you do inside it.
How a world model works
- It learns from video, not from rules. Nobody programs “gravity” into a world model. It watches enormous amounts of video — people walking, objects falling, cars turning, water flowing — and learns the statistical patterns of how scenes change from one frame to the next.
- It predicts the next frame. Given the current scene and your input (a key press, a typed instruction, a steering command), the model generates the frame that should follow. Repeat that dozens of times a second and you get a moving world.
- A planner keeps it on track. In Google’s Genie 4, a Gemini model acts as a planning agent: it reads your instructions, works out what the scene should contain, and checks each generated frame against the plan, so the world does not wander off.
- It remembers — briefly. The model holds a short memory of the scene so objects stay roughly where you left them. That memory is the weakest part: over long sessions, details drift, objects move or vanish, and the world quietly rewrites itself.
World models you can name
- Google DeepMind’s Genie 4 (announced 27 October 2026) is the most visible example: it turns a photo or a prompt into an explorable world in real time, and it is the first Genie model to generate audio natively — ambient sound, music and characters who talk back — alongside the picture. It is in a research preview for trusted testers, with Google AI Ultra subscribers and Gemini API partners to follow.
- Nvidia’s Cosmos models generate video of places that respond to actions, built for driving and robot simulation — the same family of models behind GR00T 2, the robot foundation model that learns new skills by watching human video.
- Game and film tools use the same idea at smaller scale: generate a scene, then let a player or director steer it instead of rendering it once and freezing it.
What world models are actually used for
- Training robots safely. A robot can practise picking, carrying and navigating inside a simulated world thousands of times before touching a real object — which is why world models sit next to models like Gemini Robotics 2.5, which turns instructions into movements on real factory lines.
- Training self-driving cars. Rare and dangerous situations — a child running into the road, black ice, a crash — can be simulated endlessly instead of waited for.
- Games and interactive media. Worlds that are generated rather than hand-built, and that respond to the player in ways a scripted level cannot.
- Testing AI agents. A simulated world is a safe place to watch an agent act, fail and recover before it touches anything real — the same reason agents are usually tested in sandboxes first.
- Prototyping and design. Walk through a building, a street or a set before it exists, and change it by typing.
Where world models break down
- Details drift. Google is plain about this: Genie 4 keeps a scene coherent over short sessions, but visual details and object permanence “can still shift or drift over time”. Leave a room and come back, and the furniture may have changed.
- Physics is approximate. The model has learned what falling looks like, not the laws of motion. Collisions, weight and momentum are often subtly wrong, and spatial accuracy is still listed as under research.
- Text is often unreadable. Signs, labels and writing inside generated worlds are frequently garbled — the model treats letters as shapes, not meaning.
- Audio is early. Genie 4’s native audio is a first: ambient sound and dialogue generated with the scene. DeepMind says audio accuracy is still being worked on.
- They are not reality. A world model is a prediction machine trained on video. It can be confidently wrong about how the real world works, which is why its serious uses are in simulation and training — not as a source of facts about the world. For that, you still need a language model that can show its sources.
Frequently asked questions
Is a world model the same as a video generator?
No. A video generator makes a fixed clip from a prompt; once rendered, it does not change. A world model keeps generating the next frame in response to what you do, so the scene is interactive and explorable. Video generation is one-way; a world model is a loop.
Is a world model the same as virtual reality?
No, but they overlap. Virtual reality is a way of displaying a world — a headset, a screen, a set of controls. A world model is a way of generating one. A generated world can be shown in VR, on a flat screen, or not shown at all — a robot training in simulation never sees a headset.
Can anyone use a world model today?
Barely. Genie 4 is in a limited research preview for trusted testers, with a waitlist in Project Genie; wider access for Google AI Ultra subscribers and Gemini API partners is promised as “coming soon”, with no date or price announced. Nvidia’s Cosmos models are openly available for developers building driving and robotics simulations. For most people, world models are still something to watch, not something to use.
Will world models replace game engines or film sets?
Not soon, and probably not entirely. A generated world is cheap and flexible but unreliable — a director cannot shoot a scene twice and get the same world, and a game designer cannot guarantee the level a player sees. The likely near-term role is prototyping, background generation and training, with hand-built work keeping the parts where consistency matters.
The bottom line
A world model is an AI that has watched enough of the world to fake its behaviour convincingly, one frame at a time — and the fake is now good enough to train robots, test cars and build explorable places from a sentence. Its limits are honest ones: short memory, approximate physics, drifting details. Judge any world-model claim by the same test as any AI claim: what can it do repeatedly, in front of someone who is not selling it, and what does it quietly get wrong?
Sources
- Google DeepMind — “Genie 4: A new generation of world simulation” (27 October 2026): https://deepmind.google/blog/genie-4-a-new-generation-of-world-simulation/
- FreshSynapse — “Nvidia’s GR00T 2 Teaches Robots New Skills by Watching Human Video”: https://freshsynapse.com/articles/nvidia-groot-2-robot-foundation-model-2026-11-10/
- FreshSynapse — “Gemini Robotics 2.5 Puts Humanoids on Mercedes-Benz Lines — 96% Success, With the Fine Print Attached”: https://freshsynapse.com/articles/google-gemini-robotics-2-5-2026-11-11/
- FreshSynapse — “What Is an AI Agent? A Plain-English Guide to How AI Agents Work”: https://freshsynapse.com/articles/what-is-an-ai-agent/
- FreshSynapse — “What Are Large Language Models? A Plain-English Guide”: https://freshsynapse.com/articles/what-are-large-language-models/